An LLM capability is part of a service with callers, timeouts, permissions, and costs. I apply backend discipline while acknowledging that model outputs need a different kind of evaluation.
Model proposals pass through code
Start with a non-model baseline
For classification, compare a model against rules or a simpler classifier. For documentation, compare the response against retrieval alone. Define representative examples and unacceptable mistakes. A compelling demonstration does not establish consistent quality.
Keep authority in code
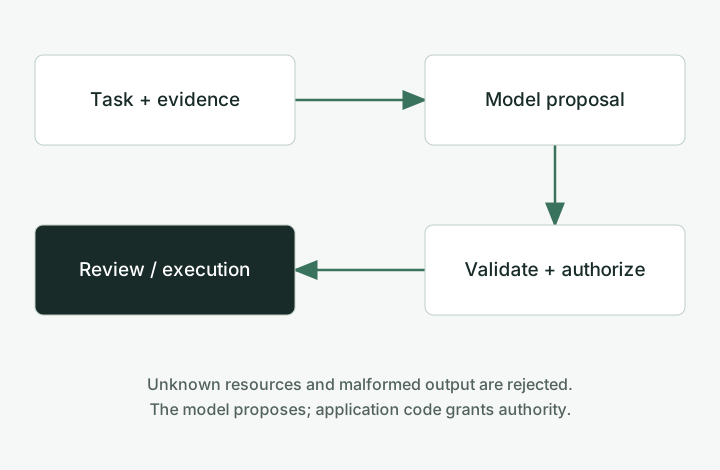
A model can propose an action. Code validates fields, authorizes the user, applies limits, and decides whether execution needs review. A generated resource identifier is not proof of access.
proposal = model.propose(task, evidence)
validate_schema(proposal)
authorize(user, proposal.resource)
validate_allowed_action(proposal.action)
if proposal.has_external_side_effect:
    require_review(proposal)
else:
    execute_with_timeout(proposal)
Evaluate failure cases
| Scenario | Expected behavior |
|---|---|
| Missing evidence | State uncertainty |
| Tool timeout | Bounded failure, no invented result |
| Unsupported citation | Reject before publication |
| Ambiguous action | Reviewable proposal |
Track outcomes alongside latency and provider-reported token usage. Schema checks test shape; human review or a carefully designed evaluator must still assess correctness.
Make failure a normal response
Use timeouts, cancellation, and retries that respect side effects. Preserve enough trace information to reproduce context and tool results without retaining unnecessary sensitive data. Evaluate prompt, model, and retrieval changes against the same suite.
Where I apply this
My workflows include repository exploration, documentation, analysis, and study. The Backend Study Lab demonstrates evidence contracts and review gates. It is not a production benchmark.
Read the prompt and harness example
References and further reading
Primary sources for the technical concepts in this article. The examples and decisions above are my synthesis, not quotations from these sources.
- OpenAI documentationEvaluation best practices
Representative tasks, explicit criteria, and regression evaluation.
- OpenAI documentationPrompt engineering
Instructions, context, examples, and prompt evaluation.
- AWS Builders’ LibraryTimeouts, retries, and backoff with jitter
Retry load, bounded timeouts, and backoff.